

Documentation: https://kvoyager.github.io/torchsonn/
TorchSONN is a PyTorch library for building and training self-organizing deep neural networks. The network grows one layer at a time. Each layer builds candidate neurons, small functions of two or more inputs taken from the previous layers' outputs and the original features. Every candidate is fitted on the training split, and the ones with the lowest error on a held-out split (by default, a separate dev split) survive into the next layer. The search stops when adding layers stops lowering that error.
The neurons come from three families: plain polynomials, orthogonal polynomials and Gaussian radial basis functions. Once the network has grown, it can be refined: a linear output head combines the last layer's survivors, and an end-to-end pass trains every parameter of the network at once by gradient descent.
The result is a network you can read: every neuron is an explicit formula over a few named inputs, and the whole network can be drawn as a graph.
- Plain polynomials in the power
basis:
linear,linear_cov,quadratic,cubicand the multi-inputpolyquad. - Orthogonal polynomials:
legendreandchebyshev, with a configurable degree and number of inputs. They stay well conditioned at higher degrees, where the raw power basis does not. - Gaussian radial basis functions:
rbf, local bumps whose centres and widths start from k-means and are then learned.
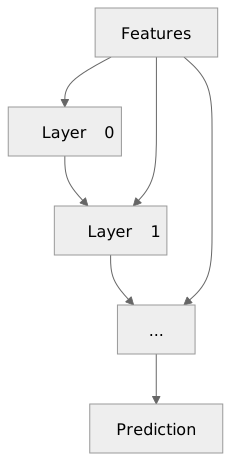
Each layer fits its candidates on the train split and keeps the
nbest_neurons with the lowest dev error. Growth stops when the dev error
stops improving, and the model keeps the layers up to the best one. The
prediction is read off the grown network in one of two ways:
- Best neuron (default): the single last-layer survivor with the lowest dev error becomes the output. This is the classic GMDH read-out, and it keeps the model reducible to one explicit formula.
- Linear head: with
use_output_projection, a linear layer combines several of the last layer's survivors into the prediction, which an end-to-end pass can then refine by training every parameter at once. This usually fits better, at the cost of the single-formula reading.
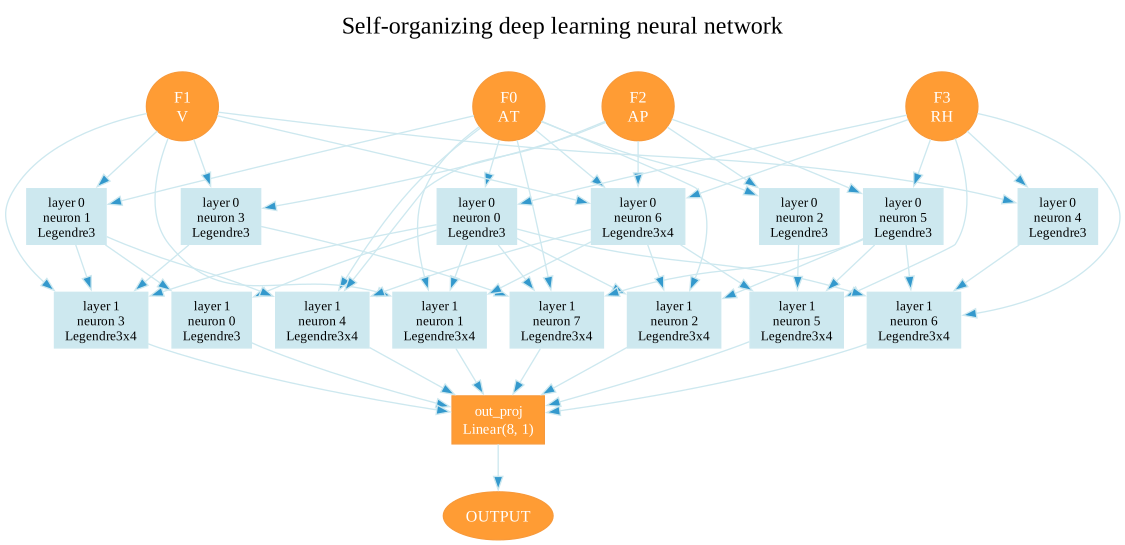
The network of the CCPP tutorial, pruned to the
neurons that reach the output. Each box is a neuron, and its incoming edges
are the inputs it reads. PlotModel draws it (see
Inspecting a model); click the image for full
size.
TorchSONN builds on the Group Method of Data Handling (GMDH) and on GmdhPy, a scikit-learn-style GMDH library. Two parts come from GMDH: the plain-polynomial neurons, and the growth itself, which fits candidates layer by layer and keeps the best by their error on a separate split. The orthogonal-polynomial and RBF neurons, the output head, the fine-tuning passes and the training on a GPU go beyond it. GMDH describes the method.
TorchSONN needs Python 3.12 or later. Install the latest release from PyPI:
pip install torchsonnPlotting is opt-in via the viz extra, which adds graphviz (for the
torchsonn.plot_model network diagrams) and matplotlib (for
SONN.plot_layer_error):
pip install "torchsonn[viz]"graphviz additionally requires the system Graphviz binaries — dot must be
on your PATH (see graphviz.org/download).
Training and inference work without any of this.
The documentation describes the
latest release. The main branch on GitHub can be ahead of it; to install
main:
pip install "git+https://github.com/kvoyager/torchsonn.git"For development, clone the repo and install editably:
git clone https://github.com/kvoyager/torchsonn.git
cd torchsonn
pip install -e ".[test]"California housing regression on the CPU, in about two minutes:
import numpy as np
from omegaconf import OmegaConf
from sklearn.datasets import fetch_california_housing
from sklearn.preprocessing import StandardScaler
from torch.utils.data import DataLoader
from torchsonn import SONN, SONNDataset, Trainer

# The rows come grouped by location, so shuffle before splitting:
# 50% train, 25% dev, 25% test; standardize on the train rows only.
x, y = fetch_california_housing(return_X_y=True)
order = np.random.default_rng(0).permutation(len(x))
x, y = x[order], y[order]
i_train, i_dev = int(0.50 * len(x)), int(0.75 * len(x))
x = StandardScaler().fit(x[:i_train]).transform(x).astype(np.float32)
# A few rows sit hundreds of standard deviations out (population, average
# occupancy); clip them so the polynomials do not extrapolate there.
x = np.clip(x, -5.0, 5.0)
y = y.astype(np.float32)

def loader(start, stop, shuffle=False):
    dataset = SONNDataset(x[start:stop], y[start:stop])
    # One batch holds a whole split (10,320 training rows).
    return DataLoader(dataset, batch_size=16384, shuffle=shuffle)

train_dl = loader(0, i_train, shuffle=True)
dev_dl = loader(i_train, i_dev)
test_dl = loader(i_dev, None)

# Only what differs from the defaults in torchsonn.config.SONNConfig.
config = OmegaConf.merge(SONN.default_config(), {
    "model": {
        "type": "regressor",
        "ref_functions": ["linear_cov"],
        "nbest_neurons": 8,
        "max_neuron_models": 28,
    },
    "train": {
        "max_layer_count": 10,
        "steps": 500,
        "eval_step_interval": 5,
        "early_stop_patience": 1e-4,
        "early_stop_tolerance_steps": 3,
        "checkpoint_dir": "checkpoints/california",
        "optimizer": {
            "name": "lbfgs",
            "optimizer_params": {
                "lr": 0.1, "min_lr": 0.01, "history_size": 10,
            },
        },
    },
})

model, trainer = SONN(config, d_model=x.shape[1]), Trainer(config)
trainer.set_seed(config.train.seed)
trainer.train(model, train_dl, dev_dl, test_dl)
trainer.load_model_checkpoint(model, "cpu")
preds, targets = trainer.infer(model, test_dl)
print(f"test MSE: {((preds - targets) ** 2).mean().item():.4f}")
The regression and classification quickstarts walk through a model like this one step by step.
Five end-to-end examples live in the repository's
tutorials/
folder, and the tutorial pages
walk through them. Run them from a clone, each with every config key
overridable on the command line:
# Iris classification — multi-class, linear_cov neurons.
python -m tutorials.iris.iris_recognition

# California housing regression — gmdhpy-equivalent setup with LBFGS.
python -m tutorials.california_housing.california_housing

# UCI Concrete compressive-strength regression — reports MSE / MAE / R².
python -m tutorials.concrete.concrete

# UCI Combined Cycle Power Plant regression — 5×2 cross-validation, reports
# mean ± std of RMSE / MAE / R² over the 10 folds (Tüfekci & Kaya benchmark).
python -m tutorials.ccpp.ccpp

# Otto Group product classification — multi-class log loss, out_proj fine-tune.
python tutorials/otto/otto_classification.py
Hydra overrides work on any field in the schema. A few useful ones:
# Resume the newest run of the config (its run folder under train.checkpoint_dir)
python -m tutorials.iris.iris_recognition resume=true

# Swap optimizer + tune its kwargs
python -m tutorials.california_housing.california_housing \
    train.optimizer.name=adam \
    train.optimizer.optimizer_params.lr=5e-3

# Redirect Hydra's per-run output directory
python -m tutorials.iris.iris_recognition hydra.run.dir=/tmp/sonn_run
The iris and otto tutorials also ship notebook versions
(tutorials/iris/iris_recognition.ipynb and tutorials/otto/otto.ipynb)
that render the layer-error curve, the confusion matrix, and the graphviz
network diagrams inline.
Every tutorial except tutorials/otto/otto_classification.py plots its
results, so they need the [viz] extra — iris, california_housing,
concrete, and ccpp render network diagrams (graphviz), and iris plus both
notebooks call SONN.plot_layer_error (matplotlib). The otto script runs on
a base install.
Every setting has a typed default in torchsonn.config.SONNConfig, and a
configuration lists only what it changes, from Python or from a Hydra YAML
file with command-line overrides. The
configuration guide shows both, and the
configuration reference lists every key.
Released under the MIT License — see LICENSE for the full text.
If you use TorchSONN in your research, please cite it as:
@software{kolokolov_torchsonn_2026,
  author    = {Kolokolov, Konstantin},
  title     = {{TorchSONN}: A {PyTorch} Implementation of the self-organizing neural network},
  year      = {2026},
  version   = {0.1.7},
  url       = {https://github.com/kvoyager/torchsonn},
  note      = {GitHub repository}
}