Repository navigation
[Bug] Docker entrypoint hardcodes start-hugegraph.sh -t 120; make the Server startup timeout configurable #3186
Description

Bug Type (问题类型)
server status (启动/运行异常)
Before submit
- I have confirmed and searched that there are no similar problems in the historical issues and documents
Environment (环境信息)
- Server Version: master (98477f0), the
hugegraph/server:latestimage built from it; the line is unchanged since refactor(docker): migrate single-node compose from host to bridge networking #2952 (0154c06, 2026-03-20) - Backend: hstore, 3 PD x 3 Store x 3 Server on Kubernetes (Helm chart from feat(helm): add HStore deployment chart #3132)
- OS: 4-node Kind (k8s 1.35) on a 15.7 GB host, and a 4-node kubeadm cluster with 7.6 GB workers
- Data Size: n/a, the failure is at startup
Expected & Actual behavior (期望与实际表现)
Expected. The time a Server container is allowed to spend starting should be something the deployment can set. Under Kubernetes the orchestrator already owns that budget through the startup probe, so the container should not enforce a shorter one of its own, or should at least let the budget be raised.
Actual. hugegraph-server/hugegraph-dist/docker/docker-entrypoint.sh line 220 runs
./bin/start-hugegraph.sh -j "${JAVA_OPTS:-}" -t 120-t sets SERVER_STARTUP_TIMEOUT_S in start-hugegraph.sh (script default 30), and when it expires the script prints Starting HugeGraphServer failed and exits 1, which ends the container. The 120 is a literal in the entrypoint; no environment variable or argument reaches it.
Measured on 2026-09-01: 2 of 6 Server starts across two independent installs terminated this way, each after exactly 24 five-second polls, exit code 1, then recovered on the next restart. The dying container's log both times:
Connecting to HugeGraphServer (http://0.0.0.0:8080/graphs).Using G1GC ...
........................Starting HugeGraphServer failed
The Helm chart gives the Server a 450-second startup budget (startupProbe failureThreshold 90 x periodSeconds 5), sized for wait-storage.sh plus JVM start on a loaded node. That budget is unreachable: the process is gone at 120 seconds, 27 percent of it, and no probe setting can extend a process that terminates itself first.
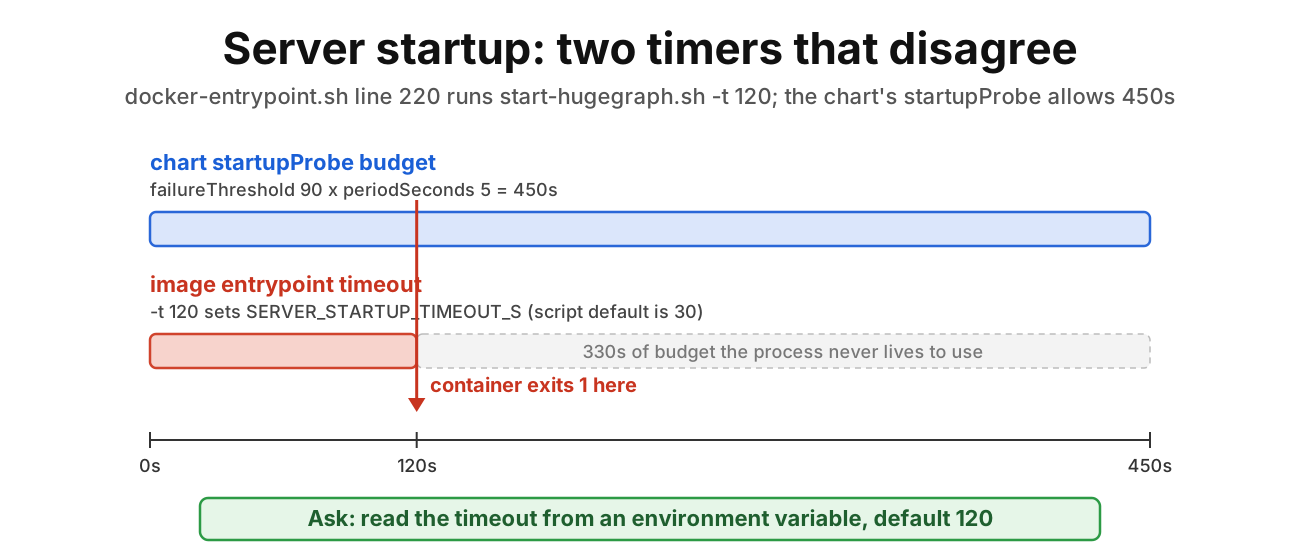
The cost today is a slow first start, not data: the container restarts and the second attempt usually succeeds because init-store has already written its marker. On a slow or contended host it can take several restarts, and every one of them looks like a crash loop to whoever is watching the rollout.
Proposal
Read the timeout from the environment, defaulting to the current value so nothing changes for anyone who does not set it:
./bin/start-hugegraph.sh -j "${JAVA_OPTS:-}" -t "${HG_SERVER_STARTUP_TIMEOUT_S:-120}"and document HG_SERVER_STARTUP_TIMEOUT_S next to the other HG_SERVER_* variables in docker/README.md. The Helm chart would then set it from the same value that sizes the startup probe, so the two timers cannot disagree. Happy to send the PR.
Related
- [Bug] Docker containers never restart when Java process crashes — broken cron monitor + tail -f /dev/null supervision #3043 covered the container not restarting after a JVM crash; this is the opposite case, the container ending a JVM that is still starting.
- refactor(docker): migrate single-node compose from host to bridge networking #2952 introduced the
-t 120line while moving the compose setup to bridge networking. - The Helm chart in feat(helm): add HStore deployment chart #3132 documents this as a limitation until the timeout is configurable.
Activity
docs(helm): document the Server image 120s startup self-termination
fix(docker): make the Server startup timeout configurable
Merge apache#3187 (0ba30a1) into helm-dev