Repository navigation
[Bug] PD /v1/health reports healthy without a raft quorum; add a quorum-aware readiness signal #3183
Description

Bug Type (问题类型)
logic (逻辑设计问题)
Before submit
- I have confirmed and searched that there are no similar problems in the historical issues and documents
Environment (环境信息)
- Server Version: master (98477f0), so this lands in 1.8.0
- Backend: hstore, 3 PD x 3 Store x 3 Server on Kubernetes (Helm chart from feat(helm): add HStore deployment chart #3132), PD image
hugegraph/pdbuilt from the same commit - OS: kubeadm 1.34 cluster, 3 worker nodes, Ubuntu 24.04
- Data Size: n/a, the problem is in cluster membership, not data
Expected & Actual behavior (期望与实际表现)
Expected. A PD that cannot take part in raft (no leader, or fewer than a quorum of members reachable) should not report itself as ready. Anything that gates on PD health, whether a Store waiting to register, wait-storage.sh on the Server, or a Kubernetes readiness probe, should be held back until the PD can actually serve.
Actual. /v1/health answers 200 as soon as the Spring listener is up and never consults the raft state. In hugegraph-pd/hg-pd-service/.../rest/StoreAPI.java:
@GetMapping(value = "/health", produces = MediaType.TEXT_PLAIN_VALUE)
public Serializable checkHealthy() {
    return "";
}
Measured on a 3-PD cluster after deleting two of the three PD pods: the survivor logged Raft lost leader within one second of the fault and then kept answering 200 to /v1/health on every one of 26 samples over about 166 seconds, while calls that need a leader failed for roughly 50 seconds until the replacements rejoined. Same process, same second, two different answers.
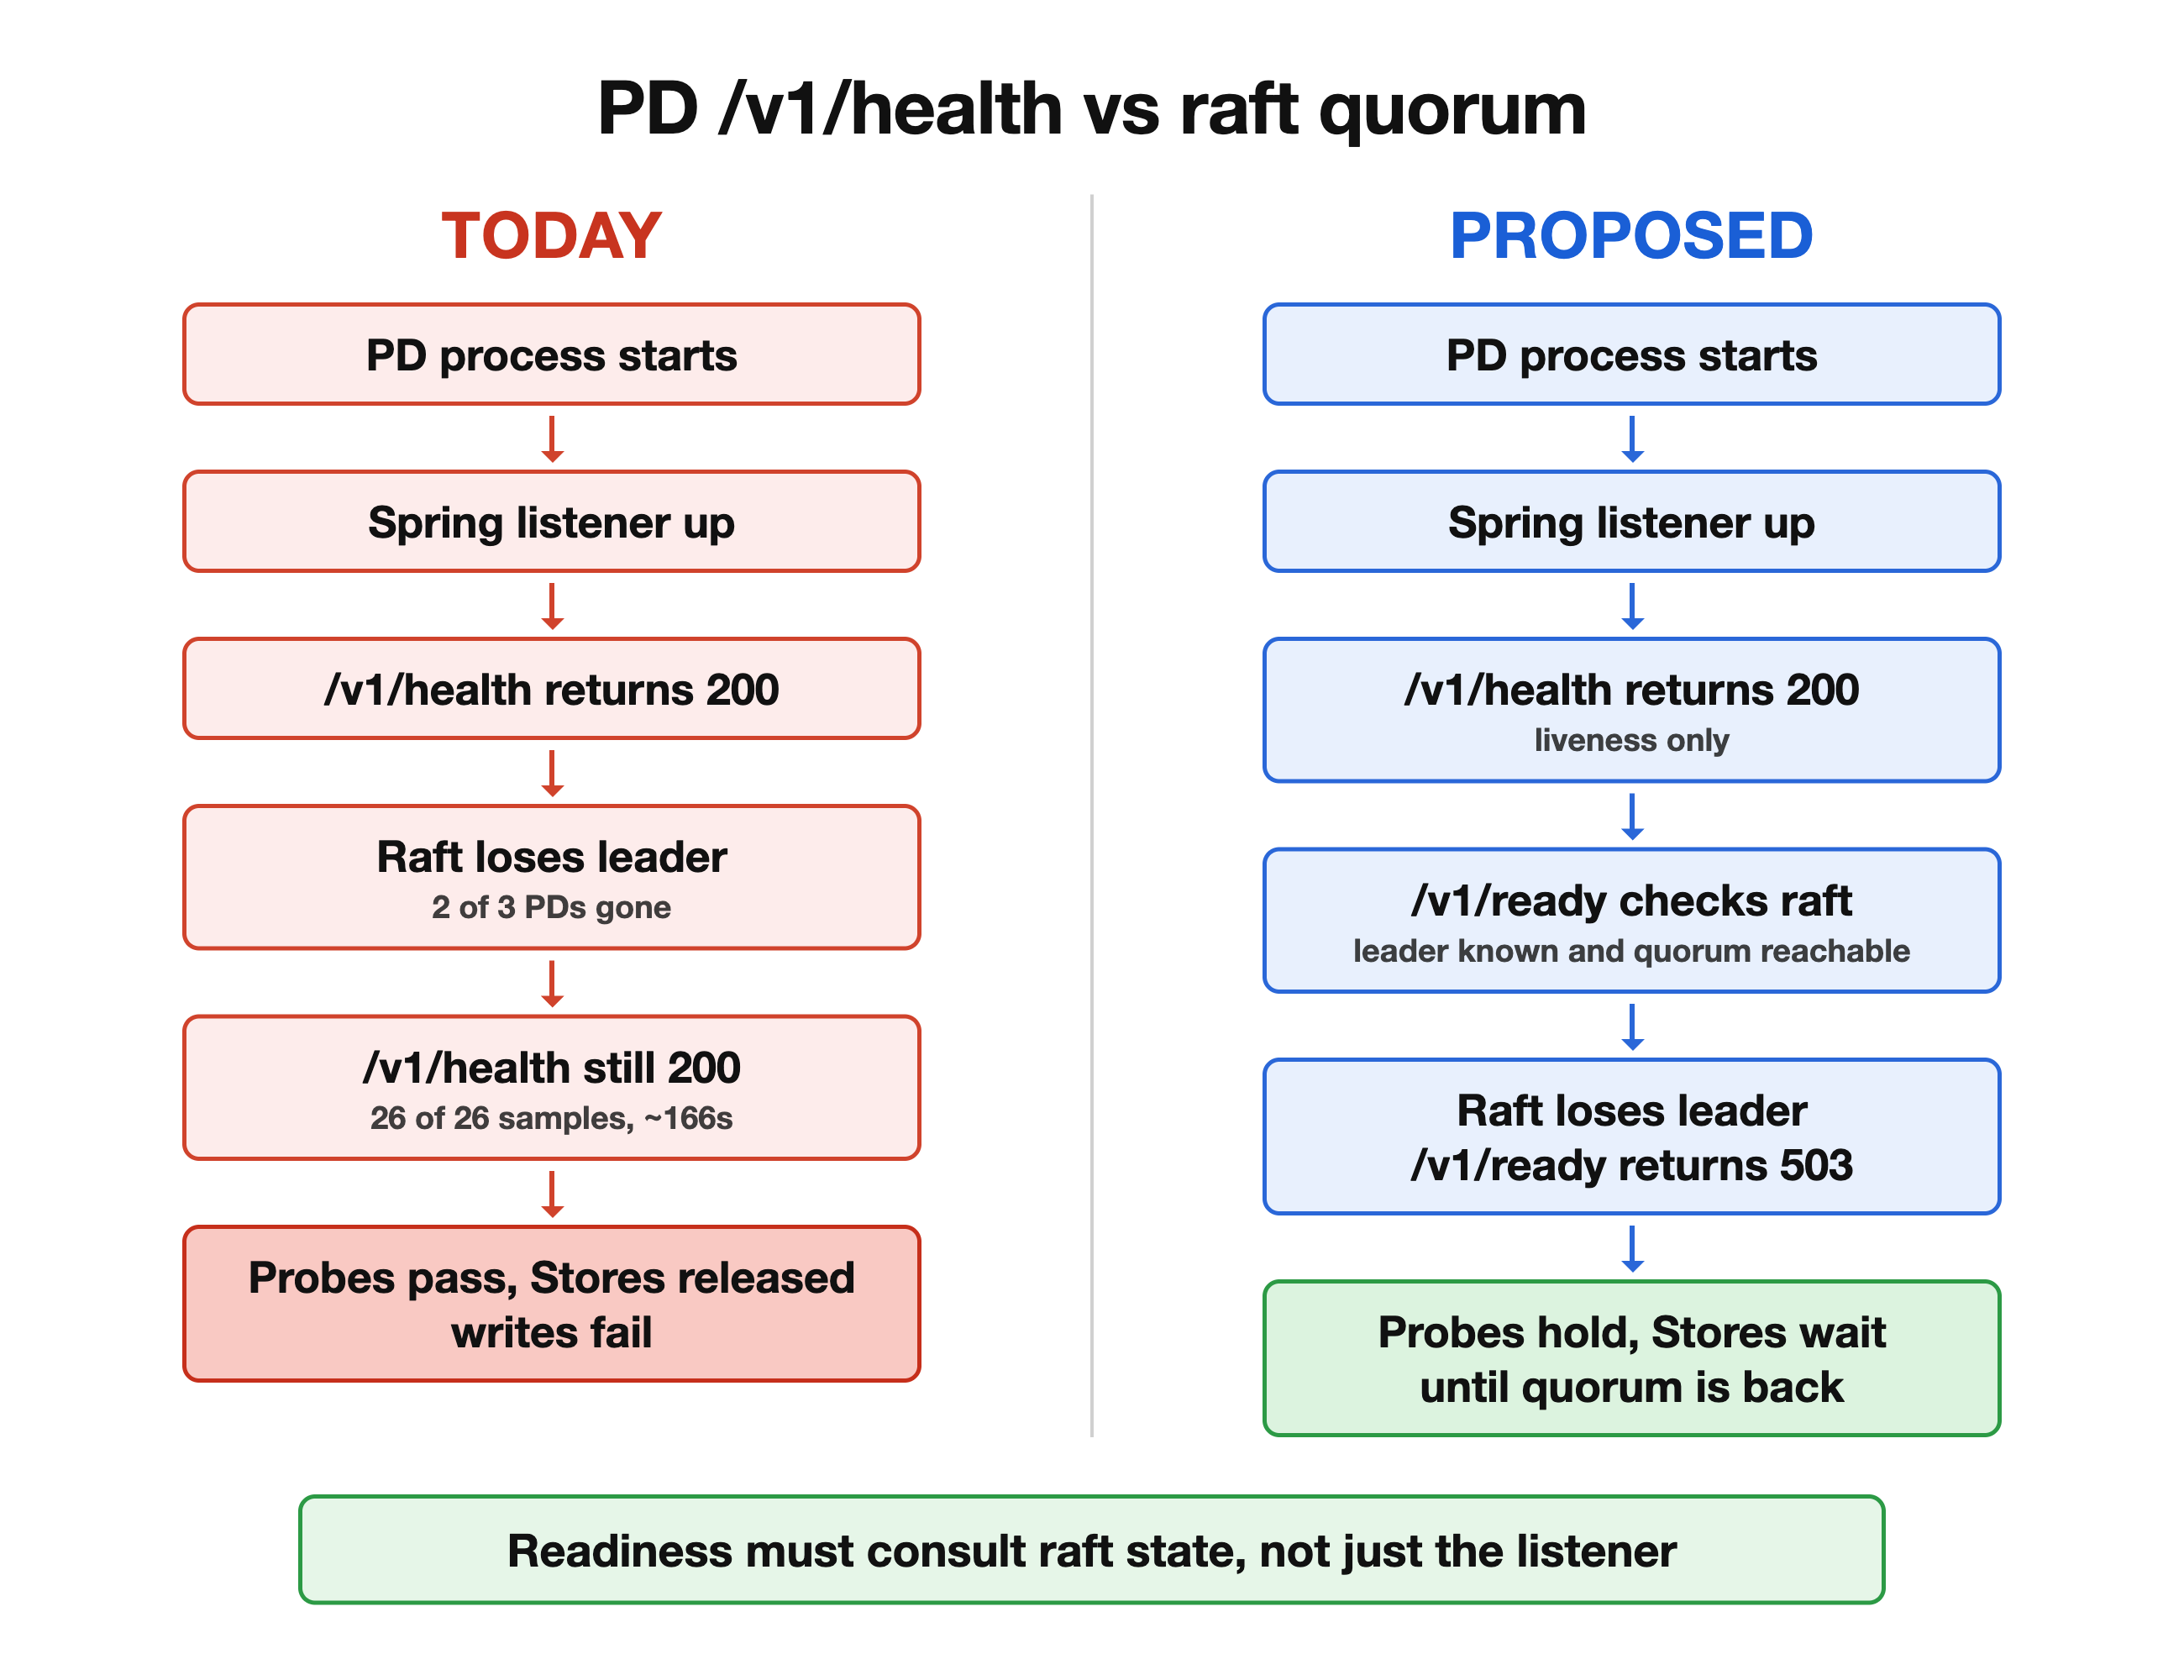
Everything that consumes /v1/health inherits the mismatch:
bin/wait-storage.shon the Server (after fix(server): retry all PD peers while waiting for storage #3129 it retries every peer, which fixed the fail-over, but a 200 from any peer still counts as "PD is up").- The Store's wait for PD before it registers.
- In the Helm chart, the startup, readiness and liveness probes on both PD and Store, and the Store init gate that waits for a quorum of PDs. That gate can release Stores against a PD that has no leader.
I looked for something else to build a real gate on and did not find an unauthenticated option:
/actuator/prometheusexposeshg_up,hg_stores,hg_termsandhg_graphs. There is no leader flag and no member count, andhg_termsread 0 on a live leader, so it cannot stand in for one./v1/membersdoes carry what is needed (pdLeaderwithroleandstate, plus the member list) but it sits behind the REST auth interceptor. A kubelet probe cannot send a credential and should not have to.
Proposal
Any of these would close the gap, listed in order of how little they change:
- Make
/v1/healthreturn a non-2xx status when the local node has no raft leader or is not part of a quorum. This is the smallest change but it turns a liveness signal into a readiness one, which may not be what every caller wants. - Keep
/v1/healthas pure liveness and add an unauthenticated/v1/ready(or/v1/health?ready=true) that returns 200 only when the node has a leader and is inside a quorum. The Helm chart andwait-storage.shwould switch to it. - Independently of 1 or 2, add a raft leader gauge (1 on the leader, 0 elsewhere) and a reachable-member count to the actuator metrics so operators can alert on quorum loss.
Option 2 plus 3 seems like the right shape. Happy to send a PR for whichever direction is preferred.
Related
- [Bug] wait-storage.sh binds to the first PD answering /v1/health and never fails over to other peers #3123 and fix(server): retry all PD peers while waiting for storage #3129 fixed
wait-storage.shsticking to one peer. This issue is the remaining half: the signal it now polls on every peer does not mean what the script needs it to mean. - The Helm chart in feat(helm): add HStore deployment chart #3132 documents this as a limitation and keeps all probes on
/v1/healthuntil a quorum-aware endpoint exists.
Activity
dosubot commentedon Sep 2, 2026
@bitflicker64 — your analysis checks out against the code on master.
checkHealthy()returns a bare empty 200 with zero raft awareness [1], exactly as you described.The building blocks for a quorum-aware endpoint already exist in
RaftEngine:isLeader()gives a per-node "am I the leader" check, andgetLeader()→raftNode.getLeaderId()tells whether the node knows who the leader is at all.getMembers()is what backs/v1/memberstoday — it lists peers, resolves their gRPC addresses, and tags each with a role and state. That endpoint sits behind auth because the interceptor exclusion list only covers/actuator/*,/v1/health, and/v1/prom/targets/*.PDMetrics.registerMeters()registers onlyhg.up(hardcoded to 1),hg.graphs,hg.stores, andhg.terms. There is no leader gauge and no reachable-member count.hg.termsis a partition-term counter (setTerms()), not a raft-quorum signal, confirming it can't substitute for one.This is the continuation of the gap flagged in #3123, which explicitly suggested "splitting liveness from readiness… with readiness backed by something raft-aware such as
RaftEngine.getLeaderGrpcAddress()" [2]. #3129 then fixed thewait-storage.shpeer-pinning problem by probing/v1/storesacross every peer on each retry [3], but as you note that only fixed peer stickiness — a storeless/leaderless PD still answers 200 to/v1/health.A related effort in #3136 requests raft-lag and recovery metrics on the Store side [4], which is a good precedent for how a leader/quorum gauge could be shaped on PD, though it doesn't cover PD's own raft state. I didn't find an existing PR or issue that adds the
/v1/readyendpoint or the leader/quorum gauges specifically, so this appears to be new ground.Given that
isLeader(),getLeader(), andgetMembers()already exist inRaftEngine, option 2 (a dedicated unauthenticated/v1/ready) looks straightforward — it would call those existing methods and skip auth the same way/v1/healthalready does. Pairing that with option 3 (ahg.pd.leadergauge and ahg.pd.reachable_memberscounter inPDMetrics) would give both the programmatic readiness gate and the alerting signal operators need.To reply, just mention @dosu.
Share context across your team and agents. Try Dosu.
feat(helm): make PD readiness and Store wait paths configurable, docu…
feat(pd): add quorum-aware /v1/ready endpoint and raft gauges
Merge apache#3185 (7074440) into helm-dev